In this blog, we’ll cover the full-text search capabilities available in the latest major release of Neo4j.
Unlike our usual blogs, this post focuses on the underlying search engine Neo4j uses: Apache Lucene 5.5.5.
What exactly is search?
Search is an interaction between a user and a search engine. The user has an information need and tries to satisfy it by providing a search with adequate constraints.
The search engine uses those constraints to collect matching results and return them to the user.
What is a search engine?
A search engine’s purpose is to store, find, and retrieve content. Neo4j uses Apache Lucene as its underlying search engine, a free and open-source information retrieval software library.
Below are some key search-engine concepts.
Document
In search applications, the notion of a Document is central, because Documents are the items being stored, searched, and returned. Documents correspond to content such as products in a catalog, book content, the result of a PDF text extraction, or people’s profiles.
A Document contains data fields, typically keys holding data values.
Inverted index
An inverted index is the search engine’s data structure. Simply put, it maps documents to keywords just like a glossary at the end of a book.
It has two main parts: a term dictionary and a postings list. The term dictionary is a sorted list of all terms that occur in a given field across the corpus. The term dictionary assigns a unique identifier to each term. The postings list is the mapping between each term (referred to by ID) and the list of documents in which it appears.
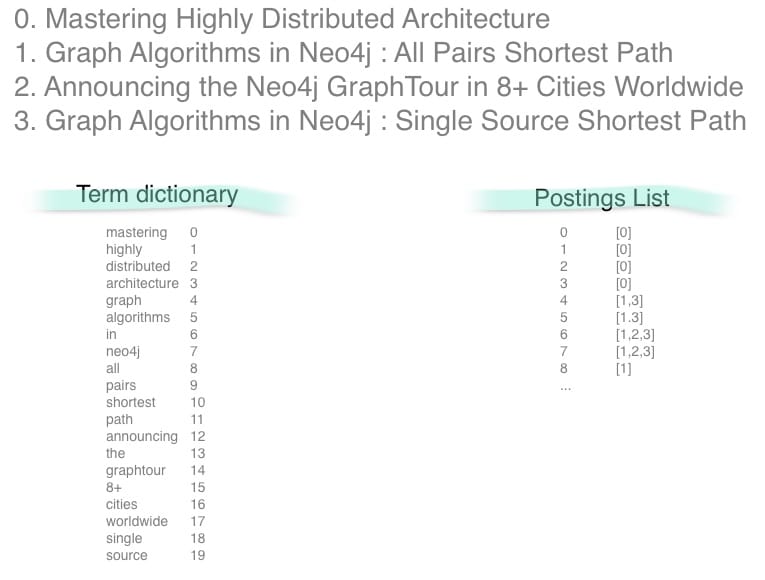
To serve relevant results, Lucene adds more data structures and metadata to the index; we’ll cover some of them later in this blog. For the impatient, they include document frequency, term frequency, term positions, term offsets, and more.
Analysis
Analysis is the process of converting text into smaller, precise units for searching: tokens.
Analysis has three steps: character filtering, tokenization, and token filtering.
Let’s go over each step and demonstrate end-to-end how we analyze the text The GraphAware’s fifth year anniversary at the Prague office in Žitná".
In the first step, character filtering, we adjust or filter characters in text fields in different ways.
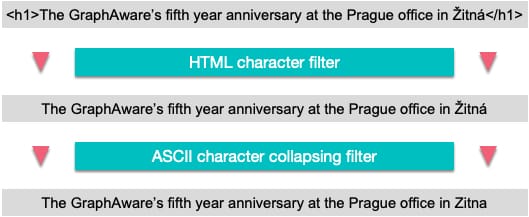
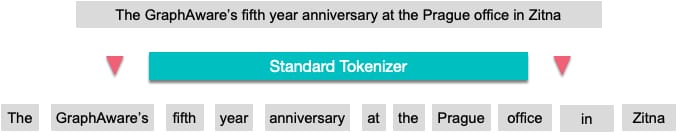
The next step is tokenization. As the name suggests, this step converts raw text into tokens. The most straightforward way to tokenize text is to split it on whitespace, but it is rarely the right approach because you end up with tokens containing punctuation, such as commas.
Instead, English and most European languages use a standard tokenizer that splits on word boundaries, whitespace, and punctuation.
The last step is token filtering. Here, tokens are adjusted by adding, removing, or changing them. To normalize the tokens in our example, a typical choice is to lowercase the tokens, remove common words such as ‘the’ and ‘at’ (usually called stopwords), and remove the possessive after GraphAware.
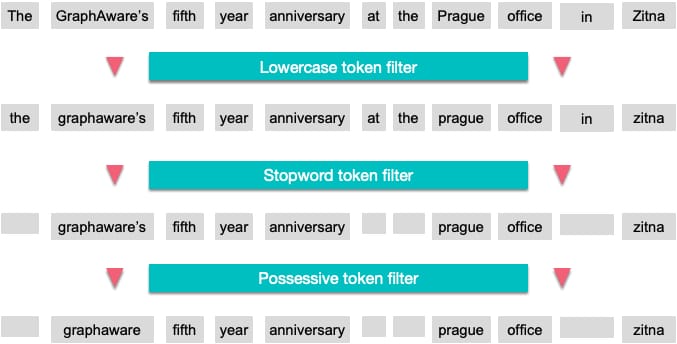
Once the analysis is completed, the data is saved in the inverted index as described above.
Searching
Once the index is built, we can search that index using a Query and an IndexSearcher. The IndexSearcher is hidden in the Neo4j implementation, so we will only go over the Query syntax.
The query syntax used is the Apache Lucene Classic Query syntax. Let’s go over some examples:
hello: search for documents containing the term hellotitle: neo4j: search for documents containing the term neo4j in the title fieldgraph*: search for documents containing terms starting with graph, such as graph, graphs, graphical, etc.
The human-readable query is parsed by Lucene’s Query Parser and is then transformed into a concrete implementation of the Query class, for which we need some understanding and examples :
| Matches documents between the beginning and ending terms, including or excluding the endpoints | Purpose | Example |
|---|---|---|
| Term Query | Single term query | neo4j |
| PhraseQuery | Match of several terms in sequence, or in near vicinity to each other | “graph database” |
| RangeQuery | Matches documents between beginning and ending terms, including or excluding the endpoints | [A TO Z] {A TO Z} |
| WildcardQuery | Regex-like query | g*p? , d??abase |
| PrefixQuery | Matches all terms beginning with a specified string | algo* |
| FuzzyQuery | Levenshtein algorithm for closeness matching | cipher~ |
| BooleanQuery | Aggregates other query instances into complex expressions | graph AND “shortest path” |
Full text search with Neo4j
We will now see how all of the above is available in Neo4j through dedicated Cypher procedures. To do so, we need to populate our database with some data, in this case, a list of book titles:
LOAD CSV WITH HEADERS FROM "https://bit.ly/fts-books" AS row
CREATE (n:Book {title: row.title, isbn: row.isbn, id: row.id, image: row.small_image_url, authors: row.authors})
Indexing
The first operation to do is to create a full-text search index, with the help of the following procedure :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])The first argument is the index name; the second argument is a list of node labels that will be represented as documents in the books index. The last argument is the list of properties to be replicated as document fields; note that as of now, only text properties are being replicated.
There is an optional fourth argument that takes a configuration map, where you can specify the analyzer to be used. The analyzer is the class that will split the text into tokens; it primarily consists of tokenizers and filters. Different analyzers will have different combinations of tokenizers and filters.
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title'], {analyzer: "spanish"})You can find the list of available analyzers with the following procedure :
CALL db.index.fulltext.listAvailableAnalyzersThe most commonly used analyzers are
- StandardAnalyzer (one of the most sophisticated analyzers; it lowers the text and removes stopwords and punctuation. It can also recognize emails and URLs)
- StopAnalyzer (same as StandardAnalyzer but without the ability to recognize emails and URLs)
- KeywordAnalyzer (tokenizes the input as a single token, useful for IDs or zip codes)
You can check the index is created by issuing the :schema command :
Indexes
   ON NODE:Book(title) ONLINE

No constraints
Querying
Now that our book index is created, we can query it and test our full-text search queries. Let’s find all books containing the word “secret” in their title :
CALL db.index.fulltext.queryNodes('books', 'secret')╒══════════════════════════════════════════════════════════════════════╤══════════════════╕
│"node" │"score" │
╞══════════════════════════════════════════════════════════════════════╪══════════════════╡
│{"image":"https://images.gr-assets.com/books/1327873635s/2998.jpg","ti│1.7604600191116333│
│tle":"The Secret Garden","isbn":"517189607","authors":"Frances Hodgson│ │
│ Burnett"} │ │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1473454532s/37435.jpg","t│1.4083679914474487│
│itle":"The Secret Life of Bees","isbn":"142001740","authors":"Sue Monk│ │
│ Kidd"} │ │
└──────────────────────────────────────────────────────────────────────┴──────────────────┘As you can see, the result of the procedure is not a list of documents, but a list of nodes instead.
There is a concept we did not cover yet: scoring. Let’s first show some examples of other queries before diving into it.
Let’s now search for secret life :
CALL db.index.fulltext.queryNodes('books', 'secret life')

╒══════════════════════════════════════════════════════════════════════╤══════════════════╕
│"node"                                                                │"score"           │
╞══════════════════════════════════════════════════════════════════════╪══════════════════╡
│{"image":"https://images.gr-assets.com/books/1473454532s/37435.jpg","t│1.9917329549789429│
│itle":"The Secret Life of Bees","isbn":"142001740","authors":"Sue Monk│                  │
│ Kidd"}                                                               │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1320562005s/4214.jpg","ti│0.6224165558815002│
│tle":"Life of Pi","isbn":"770430074","authors":"Yann Martel"}         │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1327873635s/2998.jpg","ti│0.6224165558815002│
│tle":"The Secret Garden","isbn":"517189607","authors":"Frances Hodgson│                  │
│ Burnett"}                                                            │                  │
└──────────────────────────────────────────────────────────────────────┴──────────────────┘
As you can see, the second result does not contain all of the search terms. This is because when the query is parsed, it is understood as a TermsQuery, where each term is handled separately.
To circumvent this, we can force the query to be understood as a PhraseQuery by enclosing the terms in double quotes :
CALL db.index.fulltext.queryNodes('books', '"secret life"')

╒══════════════════════════════════════════════════════════════════════╤══════════════════╕
│"node"                                                                │"score"           │
╞══════════════════════════════════════════════════════════════════════╪══════════════════╡
│{"image":"https://images.gr-assets.com/books/1473454532s/37435.jpg","t│2.8167359828948975│
│itle":"The Secret Life of Bees","isbn":"142001740","authors":"Sue Monk│                  │
│ Kidd"}                                                               │                  │
└──────────────────────────────────────────────────────────────────────┴──────────────────┘
We can also search on a specific field :
CALL db.index.fulltext.queryNodes('books', 'authors: rowling')

╒══════════════════════════════════════════════════════════════════════╤══════════════════╕
│"node"                                                                │"score"           │
╞══════════════════════════════════════════════════════════════════════╪══════════════════╡
│{"image":"https://images.gr-assets.com/books/1474154022s/3.jpg","title│1.7578392028808594│
│":"Harry Potter and the Sorcerer's Stone (Harry Potter, #1)","isbn":"4│                  │
│39554934","authors":"J.K. Rowling, Mary GrandPré"}                    │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1387141547s/2.jpg","title│1.7578392028808594│
│":"Harry Potter and the Order of the Phoenix (Harry Potter, #5)","isbn│                  │
│":"439358078","authors":"J.K. Rowling, Mary GrandPré"}                │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1474169725s/15881.jpg","t│1.7578392028808594│
│itle":"Harry Potter and the Chamber of Secrets (Harry Potter, #2)","is│                  │
│bn":"439064864","authors":"J.K. Rowling, Mary GrandPré"}              │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1361482611s/6.jpg","title│1.7578392028808594│
│":"Harry Potter and the Goblet of Fire (Harry Potter, #4)","isbn":"439│                  │
│139600","authors":"J.K. Rowling, Mary GrandPré"}                      │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1474171184s/136251.jpg","│1.7578392028808594│
│title":"Harry Potter and the Deathly Hallows (Harry Potter, #7)","isbn│                  │
│":"545010225","authors":"J.K. Rowling, Mary GrandPré"}                │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1361039191s/1.jpg","title│1.7578392028808594│
│":"Harry Potter and the Half-Blood Prince (Harry Potter, #6)","isbn":"│                  │
│439785960","authors":"J.K. Rowling, Mary GrandPré"}                   │                  │
├──────────────────────────────────────────────────────────────────────┼──────────────────┤
│{"image":"https://images.gr-assets.com/books/1499277281s/5.jpg","title│1.3183794021606445│
│":"Harry Potter and the Prisoner of Azkaban (Harry Potter, #3)","isbn"│                  │
│:"043965548X","authors":"J.K. Rowling, Mary GrandPré, Rufus Beck"}    │                  │
└──────────────────────────────────────────────────────────────────────┴──────────────────┘
Or on more than one field :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])Fuzziness
The power of Full Text Search is also the ability to retrieve results even if the search query does not exactly match text in the original corpus.
A couple of implementations offer this behavior; one is FuzzyQuery.
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])The tilde (~) allows a FuzzySearch for garde using the Damerau-Levenshtein distance algorithm. As you can see, some results, such as The Hitchhiker's Guide to the Galaxy (Hitchhiker's Guide to the Galaxy, #1 are not really relevant for our search; this is because of the default minimum term similarity set for the FuzzyQuery, which is 0.5. You can override the default with your own minimum by specifying it after the tilde :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])Proximity search
If you think about the use case for FuzzySearch, you can imagine we would encounter the same need with PhraseQuery searches, where the sequence of terms in the query may not match the original corpus exactly.
The following search will return nothing, even though we have a book with the title The secret life of bees :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])You can specify the distance between the words specified in the search query, for example :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])WildcardQuery
The last implementation we will cover is the WildcardQuery, where you can provide wildcards for your searches.
Use ? for a single-character wildcard search, use * for a multiple-character wildcard search.
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])Scoring
The default scoring function of Apache Lucene, at least in version 5.5.5, is based on a highly optimized Vector Space Model. That scoring function is more commonly known as TFIDF Similarity.
From Wikipedia :
In information retrieval, tf–idf or TFIDF, short for term frequency–inverse document frequency, is a numerical statistic that is intended to reflect how important a word is to a document in a collection or corpus.
Term frequency
The term frequency is the raw count of a term in a document (the number of times the term t appears in document d).
Inverse document frequency
The inverse document frequency is a measure of how much information the word provides (ie, if it’s common or rare across the corpus).
The formula for calculating the idf is the following :

where :
Nis the total number of documents in the corpus|{d ∈ D : t ∈ d}|is the number of documents where the termtappears
Term-frequency inverse document frequency
The TF-IDF is calculated as

There are some variations and adaptations in the concrete implementation of TF-IDF in Lucene, but you have the basic idea of the most common similarity computation function used in information retrieval. For a detailed explanation of TF-IDF in Lucene, you can refer to its Javadocs.
A small example sometimes explains better :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])As you can see, the importance of the term sample is higher in the first result because the text is shorter than the second result- this is the effect of the tf formula.
If we were to now create another 100 documents containing the term sample, we would encounter the idf effect, which will increase the difference in similarity between the first result and all the other results for the term sample because it appears often in many documents.
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])Boosting
Users can influence the scoring of matched results. Apache Lucene offers two types of boosting capabilities :
index time boosting: which adds a boost factor to a document before it is indexed (not possible in Neo4j)query time boosting: which applies a boost to a query
Let’s say you want the author search to be more important than the book title search. You can apply a boost near the author search terms.
To demonstrate, let’s take a Boolean query :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title', 'authors'])The first result has a higher score because it matches all the title conditions, but we can influence the authors to be of higher importance :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title'], {analyzer: "spanish"})You can apply boosting to phrase queries as well :
CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title'], {analyzer: "spanish"})CALL db.index.fulltext.createNodeIndex('books', ['Book'], ['title'], {analyzer: "spanish"})This concludes this article about the Full Text Search capabilities in Neo4j.
Suggested reading
Introduction to Information Retrieval: Manning, Raghavan & Schütze, 2007
Relevant Search: Doug Turnbull and John Berryman, 2016
Neo4j Full Text Search Documentation
Conclusion
Search is an important part of any application. Neo4j’s recent release adds this support, which has long been a community feature request.
GraphAware has been a pioneer of Graph-Aided Search, using graphs to help during relevance engineering, with implementations at Airbnb and the World Economic Forum.
This article was originally published in 2019 and reflects the full-text search functionality available in Neo4j 3.5 at the time. Some indexing procedures, Cypher syntax, and search functionality have changed in subsequent releases. The examples are retained for historical reference and may not reflect current Neo4j best practices. For up-to-date guidance, please refer to the Neo4j documentation.